The prompt trains you to say yes.
Each approval is sensible on its own. By the fortieth, "allow for this session" becomes "always allow", and nobody looks at it again.
Mockingbyrd is a macOS app that shows what the AI agents on your Mac can reach, scores your setup against a set of security rules, and blocks risky commands before they run.
DEMO MACHINE · SYNTHETIC RULE PACK
The problem
Nobody sets out to give an AI agent the run of their Mac. It happens one reasonable click at a time, and nothing tells you when the total adds up to more than you meant.
Each approval is sensible on its own. By the fortieth, "allow for this session" becomes "always allow", and nobody looks at it again.
Cleaning it up doesn't hold. New grants arrive as you work, and nothing flags the one that widens what an agent can do. The file records what was allowed, never when or why.
A rule blocking sqlite3 means little when the same list lets an agent run any Python it writes. Python opens the database just as easily.
38 "deny": [ 39 "Bash(sqlite3 *)" 40 ], 41 "allow": [ 42 "Bash(python3 -c *)" 43 ]
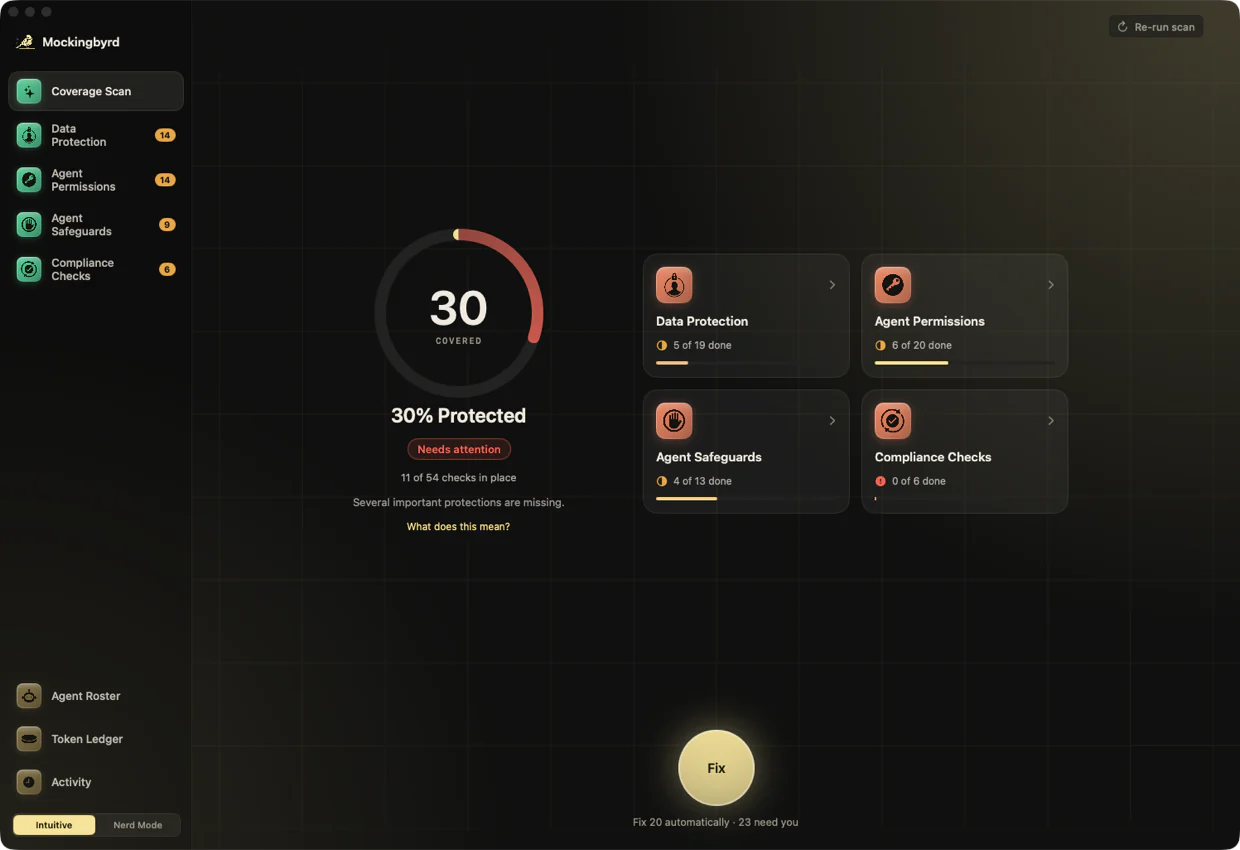
Checks run against the actual machine — permission lists, file flags, hooks, snapshots, open database handles. Each reports the evidence it found, not a green tick. The result is a weighted score you can argue with.
Every fixable finding writes a shell script and shows it to you. Read it, then apply — or run it yourself. Settings are backed up before a byte changes.
A hook inspects every tool call before it runs, reading the command and the paths it touches. It sits below the permission list, where a wildcard grant can't step around it.
Re-scans on your cadence. Says when a control that was holding stops holding, when a config file changes underneath you, when the original moves and nothing was supposed to be writing to it.
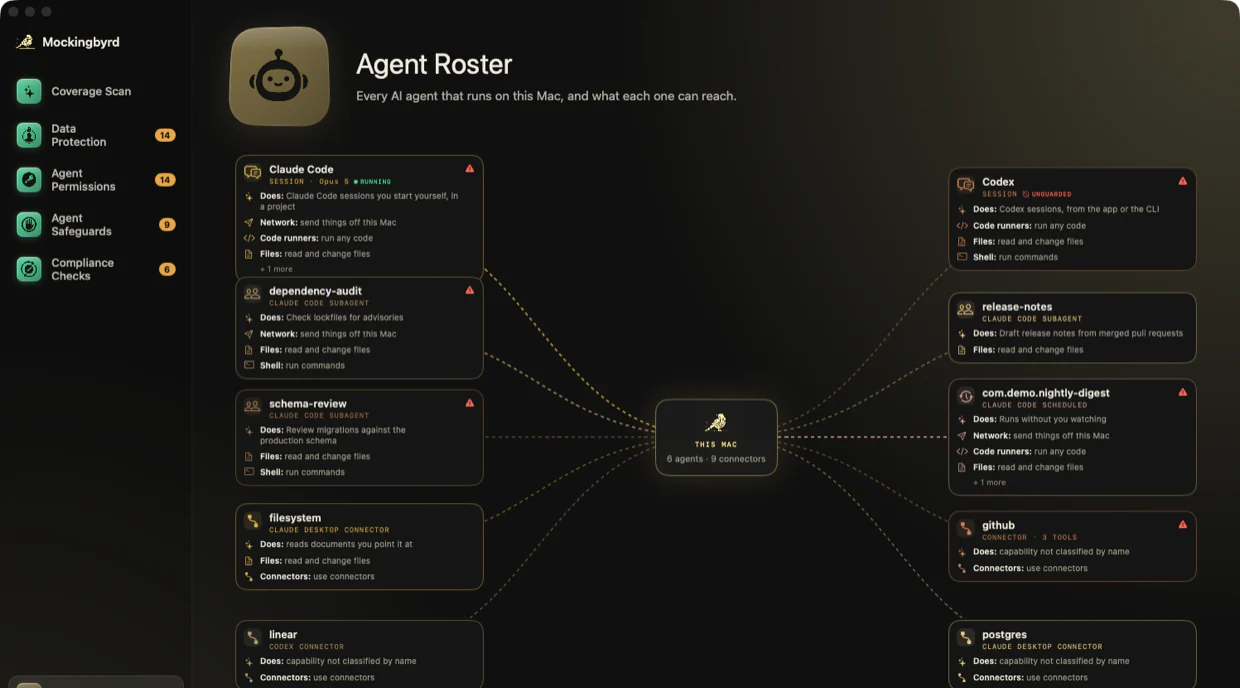
Sessions, subagents, scheduled jobs, connectors — the roster names which kind each one is rather than flattening them, and fills a cell only from something on disk: a permission entry, a profile, an agent definition, a scheduled job, a connector declaration.
The combinations that matter are named underneath each one: reads widely and can send off the machine, runs arbitrary code, runs unattended while nobody is watching.
Connectors enabled in the web app are configured server-side, so a locally declared list is a floor, not the whole picture. The roster says that on the screen rather than in a footnote.
DEMO MACHINE · SYNTHETIC AGENTS

Controls are weighted by what they cost you when they fail, so the number moves for reasons you can name. Every check shows its working.
No silent remediation. The change is written to disk as a script you can open, before anything runs it.
A permission list sitting beside a general interpreter is advice. The guard reads the command whichever interpreter would have run it.
The guard re-reads its state on every call. Pause takes effect now, resumes itself when you said it should, and keeps logging throughout — so you can see what went through while it was off.
Fingerprints on the files that matter. A control that quietly stopped holding is an event, not something you discover in a quarterly review.
Ships with one rule pack. Every rule is a shell probe you can edit, weight, disable or replace — write your own and the score follows.
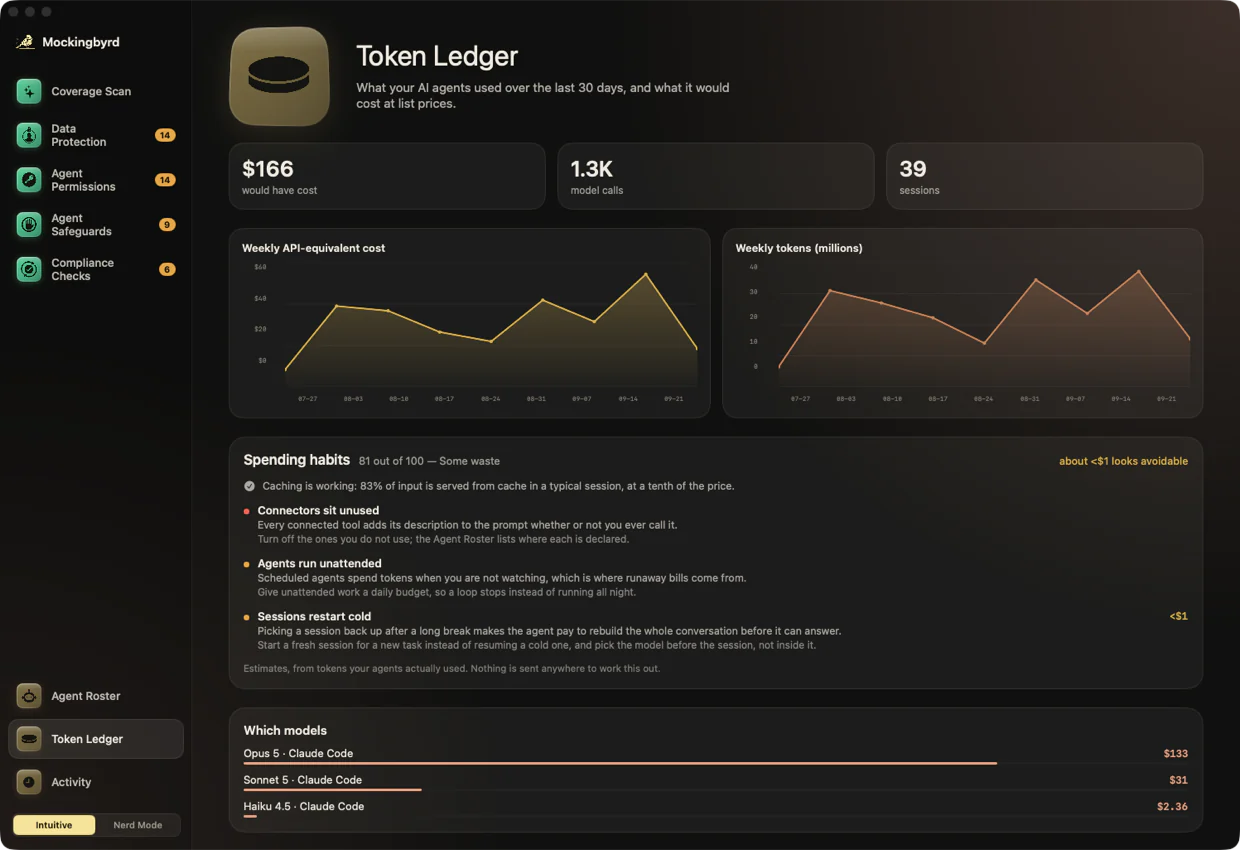
Token use and API-equivalent spend by model, by project, by week — read from the session logs your agents already write. Producing it sends nothing anywhere.
It scores the waste too: whether caching is working, connectors that sit unused while adding their description to every prompt, agents spending unwatched, and sessions picked up cold when a fresh one would have been cheaper.
It is not a bill. Consumer Claude and ChatGPT subscriptions are not billed per token — this is what the same traffic would have cost at list prices, which is a sense of proportion rather than an invoice.
DEMO MACHINE · SYNTHETIC SESSIONS

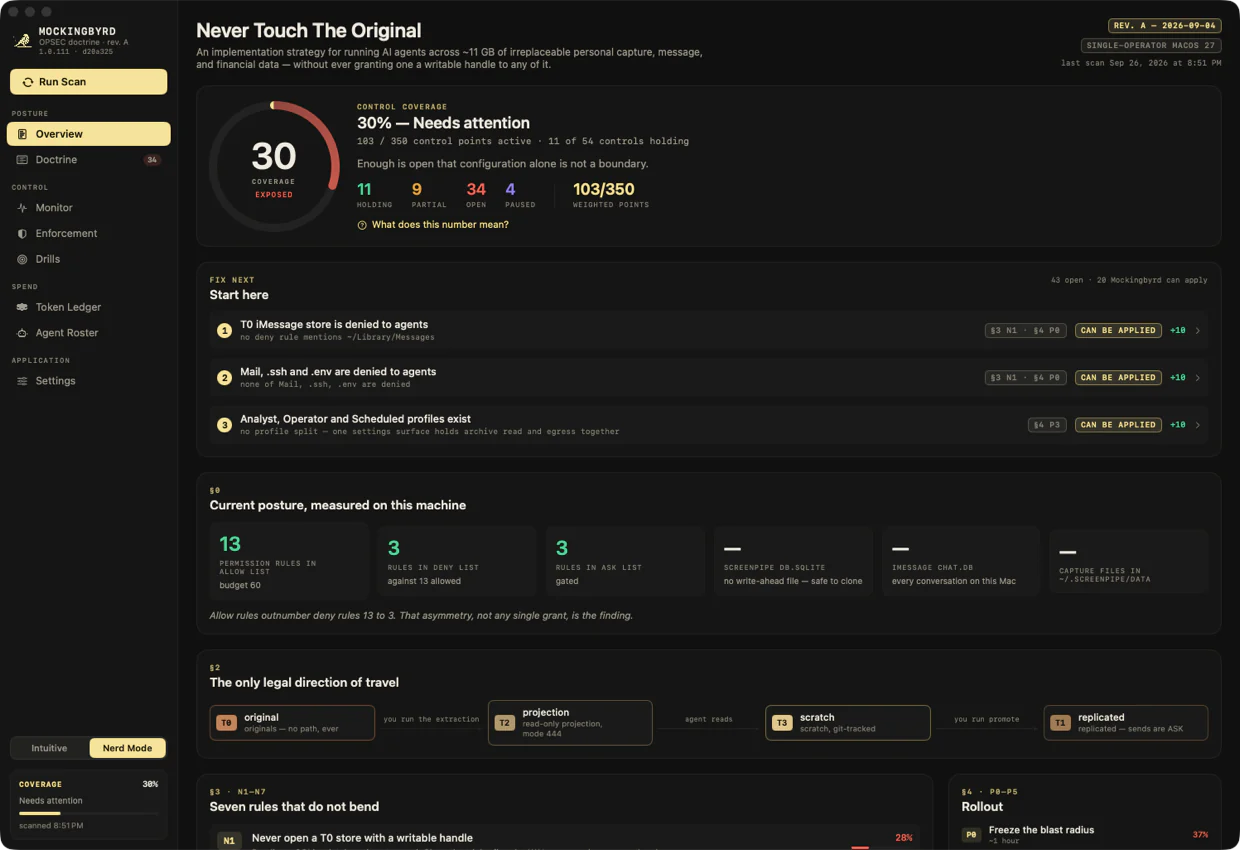
Nerd Mode is the probes, the weights and the evidence: the seven rules that do not bend, the rollout behind them, every control with the shell probe that tested it and its result across the last 24 scans.
Intuitive is plain language over identical numbers — areas instead of invariants, a card per finding, the map without the matrix, and one button that separates what can be fixed for you from what needs you.
Neither is a subset that hides a problem. The mode changes the vocabulary, not the score.


THE SAME SCAN, BOTH MODES · DEMO MACHINE, SYNTHETIC RULE PACK
Paste your Claude Code settings.json. It is scored in your browser tab and never uploaded.
Objections, handled
Including where the controls stop.
Nothing it measures. Scans, the guard and the token ledger read files already on disk, and no scan result, no file content and no license is ever sent anywhere. Three things can go out, and each is yours to switch off: an update check at launch, which fetches one static file and carries no identifier; a price-list update you trigger yourself; and crash reporting, which is off until you turn it on and then sends a stack trace with no identifier for you or your machine.
Apple silicon Macs running macOS 14 or later. The app is signed and notarized, and there is no sign-in: it runs without an account. Past the trial it needs an activation code, which means giving us an email address and the machine code shown in Settings — the only identifier we collect.
A deny rule sitting beside a wildcard interpreter grant stops an honest agent, not a redirected one. If Bash(python3 -c *) is allowed, Python can do whatever the deny rule forbids. The guard reads the command that will actually run, whichever interpreter runs it.
A block asks first: Block, Allow once, or Allow for a set number of minutes. Every answer is logged, so you can review later what went through.
Never. Every fix is written as a shell script you can read before anything runs it, and your settings are backed up before any change.
It runs as you, so an agent with a general interpreter can reach it. Doing so takes visible steps: the configuration is fingerprinted and drift is recorded. That is not isolation, and we don't claim it is.
No. It shows what the same traffic would cost at API list prices. Consumer Claude and ChatGPT subscriptions aren't billed per token, so treat it as a sense of proportion, not an invoice.